We are already at the 20th issue of Agents in Practice! Thank you for reading and supporting this newsletter. I hope to bring you more interesting research and news in the future, and focus on sharing more anecdotes from my personal work.
📬 Agents in Practice is a weekly newsletter on agentic AI research and applications. Subscribe here →
Fine-tuning by deleting weights
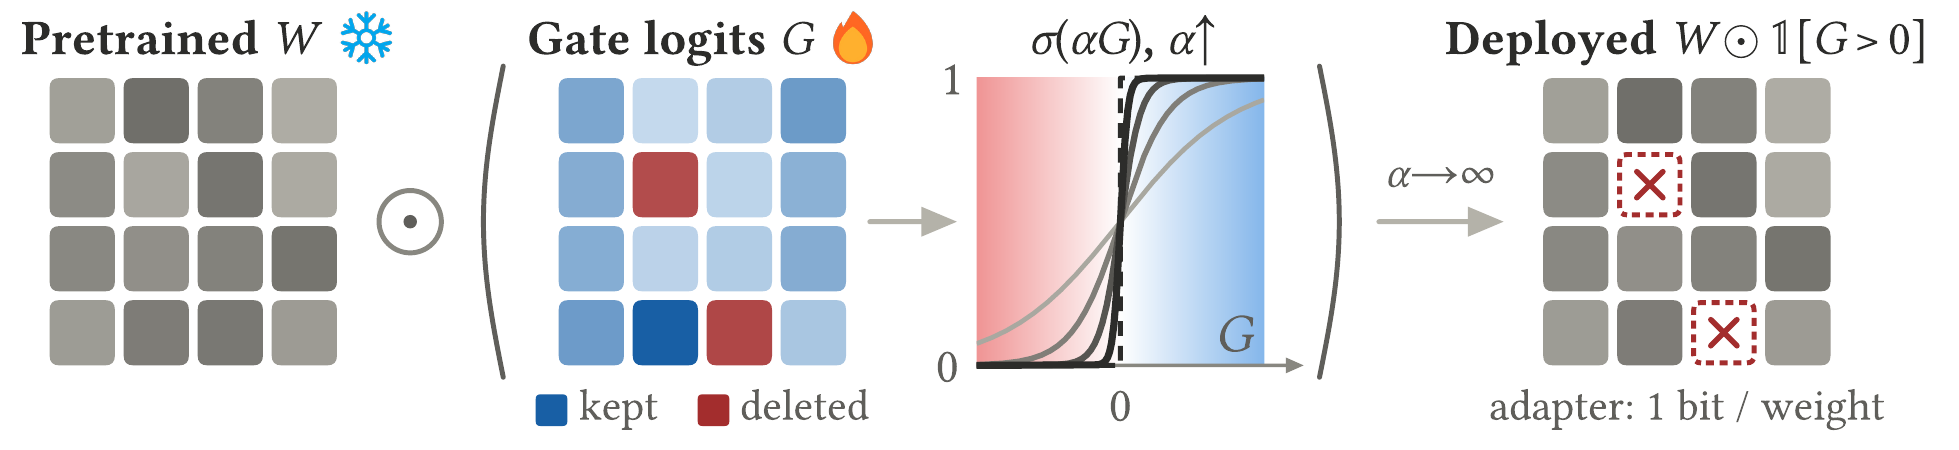
Researchers from New York University and the University of Calgary studied whether LLMs can learn new tasks by deleting weights. “Deletion Tuning” freezes the pretrained weights and learns which ones in the model’s feed-forward layers to set to zero, keeping the rest of the weights unchanged. The authors tested this with reinforcement learning, supervised fine-tuning, and self-distillation.
In their RL experiments, deleting fewer than 0.05% of the model’s weights approached full fine-tuning at larger model sizes. For Llama 3 8B, the best checkpoint reached 83.55% accuracy on GSM8K, compared with 60.27% before training and 83.24% with full fine-tuning. However, on some smaller models, Deletion Tuning performed worse than full fine-tuning.
The authors claim that Deletion Tuning also preserved more of the models’ existing abilities. Across three Llama sizes, average accuracy on six prior-task benchmarks stayed within one percentage point of the original model during reinforcement learning.
Personal Thoughts
At first, it seems counterintuitive that deleting weights could serve as a fine-tuning method, but thinking of how neural networks work, it does make sense. It is just that the numbers change to zero instead of being updated. I wonder if there will be a real-world benefit to compact mask representations of the fine-tuned model weights.
Read more
Choose how to self-improve
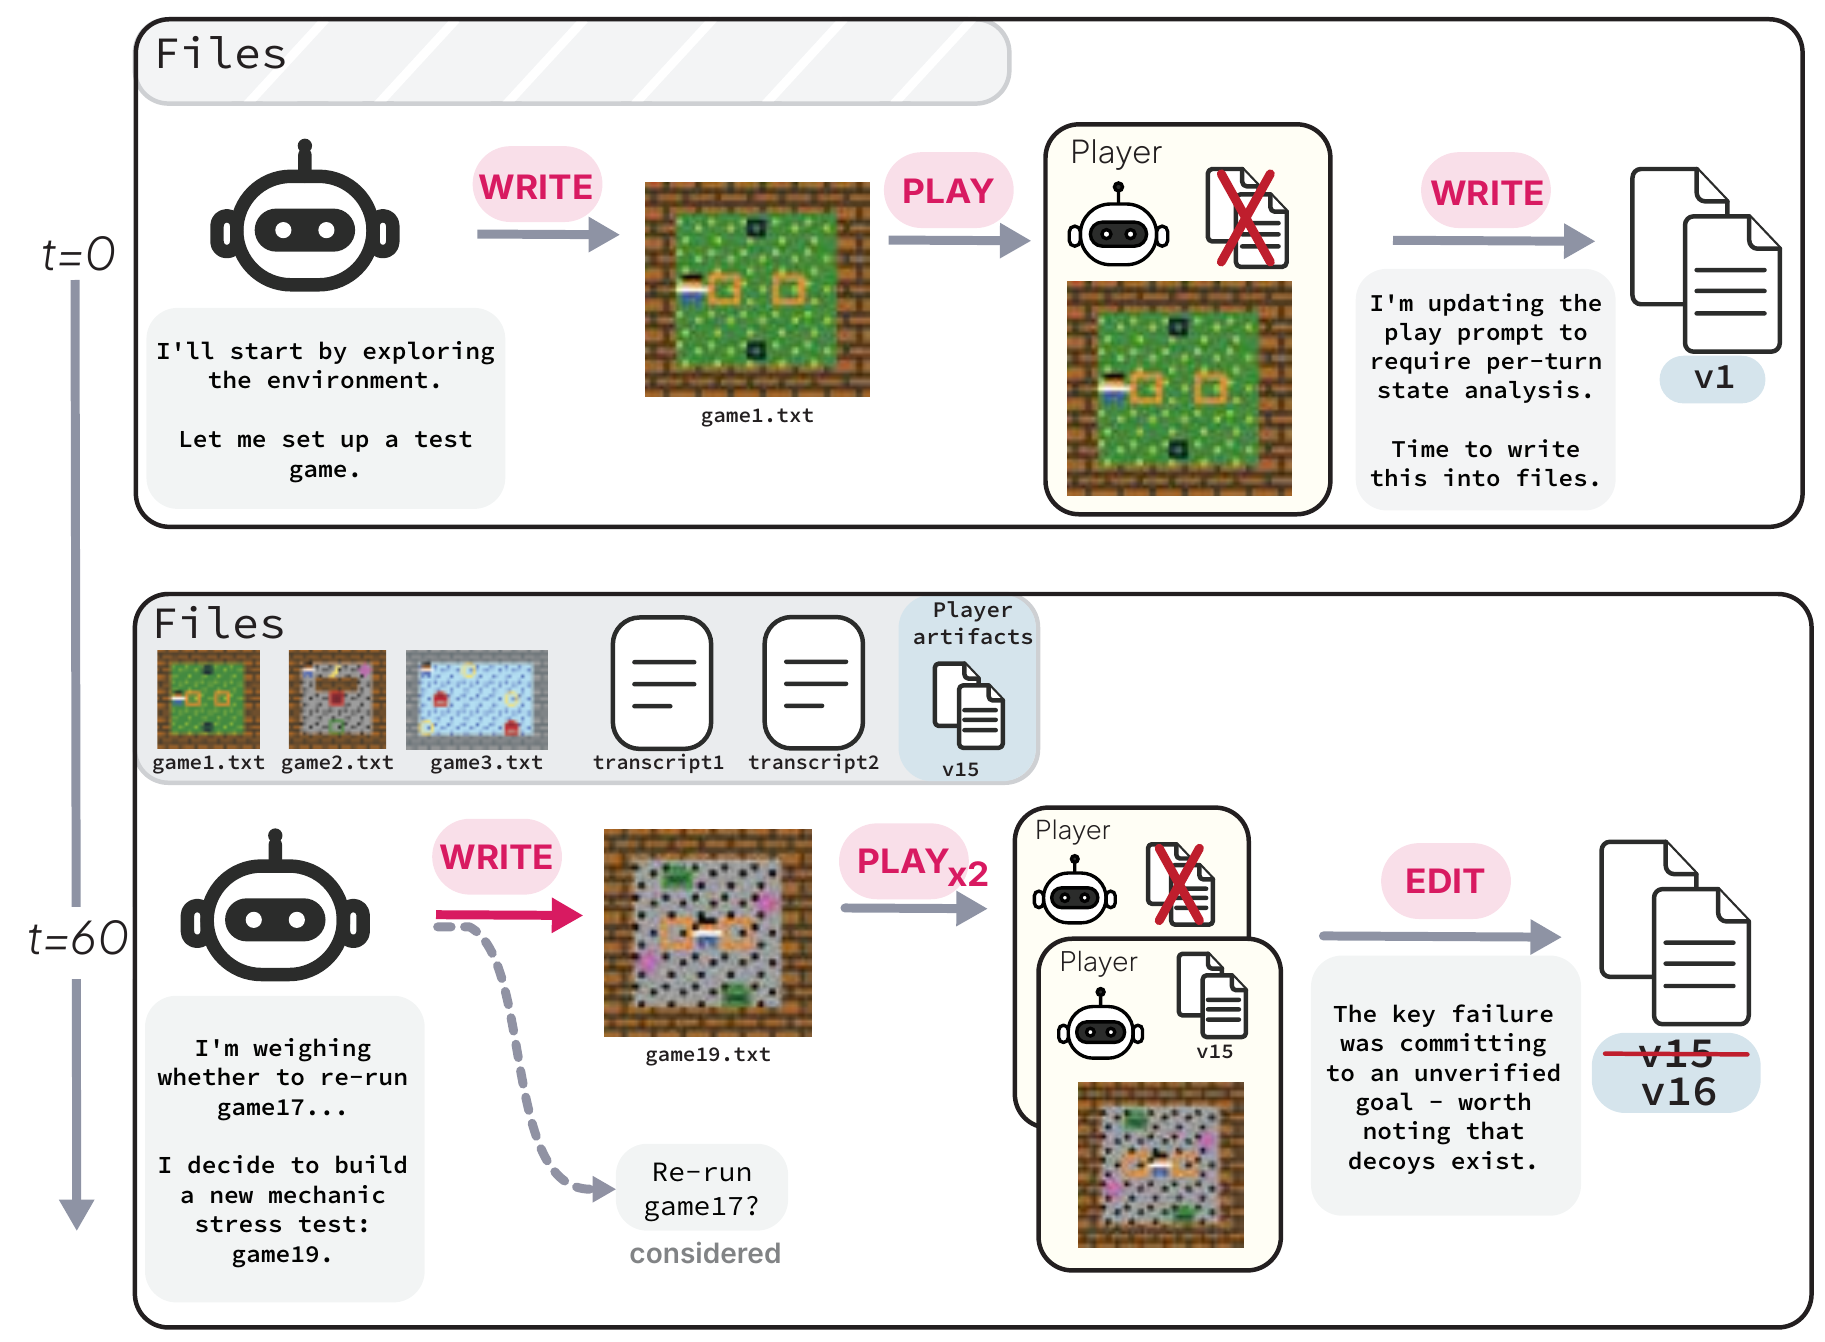
Researchers from MIT CSAIL and the University of Tübingen studied whether LLM agents can design their own learning procedures. They used two separate instances of the same model: a teacher and a player. The teacher chose how to spend its budget using tools to create practice games, observe the player’s attempts, and edit the player’s prompt and skill files. The model’s weights stayed frozen, and the teacher had no access to the evaluation games or their scores.
The authors tested six models, running three independent teacher sessions for each, with budgets of 150 gameplays and 20 edits to the player’s text files. Claude Opus 5, GPT-6 Astra, and GLM 5.3 improved on unseen PuzzleScript games, while the older model tested from each family showed little or no improvement. Successful teachers more often compared play with and without their advice and generated fewer trivial games. Some also built validation suites or designed adversarial games to test their notes.
In further experiments with Claude Opus 5, the learned text also helped on longer PuzzleScript games, Level 1 of ARC-AGI-3, and a 3D navigation benchmark.
Personal Thoughts
Recursive self-improvement has been a popular topic for a while now. There have been numerous research papers and systems built on how to build the self-improvement loop to be efficient, robust, etc. But maybe, the agent can just learn how to self-improve by itself?
Read more
One-liners
- Lots of new models as always. Meta released Muse Ember (Nov 9) for repeated agent tasks, and OpenAI released GPT-6.2 Astra and Sol (Nov 17). Alibaba released Qwen4-Max (Nov 16) through its API, Microsoft released MAI Code 2 and Code 2 Flash (Nov 17) in GitHub Copilot, and Google began rolling out Gemini 4 Neon (Nov 18) in Antigravity.
- On the open-weight side, Thinking Machines published the Inkling 2 Small weights (Nov 12). Nous Research also released Arete-27B, a version of Qwen3.8-27B post-trained to reduce Chinese state-aligned responses.
- Google DeepMind introduced AlphaProof Code (Nov 10), an agent framework that proved specified security properties of Signal’s compiled cryptographic code, with human-reviewed specifications and proofs checked by Lean.
- Microsoft reported that about two weeks of agent-assisted Linux-kernel scanning produced 26,502 raw findings (Nov 11), but turning them into reproducible bugs, patches, and 59 upstream reports took months of expert work.
Subscribe to Agents in Practice
Get new issues of Agents in Practice — a newsletter summarizing exciting new research and applications in agentic AI — delivered to your inbox.